SMTX AI Platform

Build AI-Ready Infrastructure with Ease

As enterprise AI applications move from validation to production, SMTX AI Platform helps organizations manage compute, deploy models, govern model access, and operate AI services on a unified infrastructure, accelerating the adoption of AI across business scenarios.

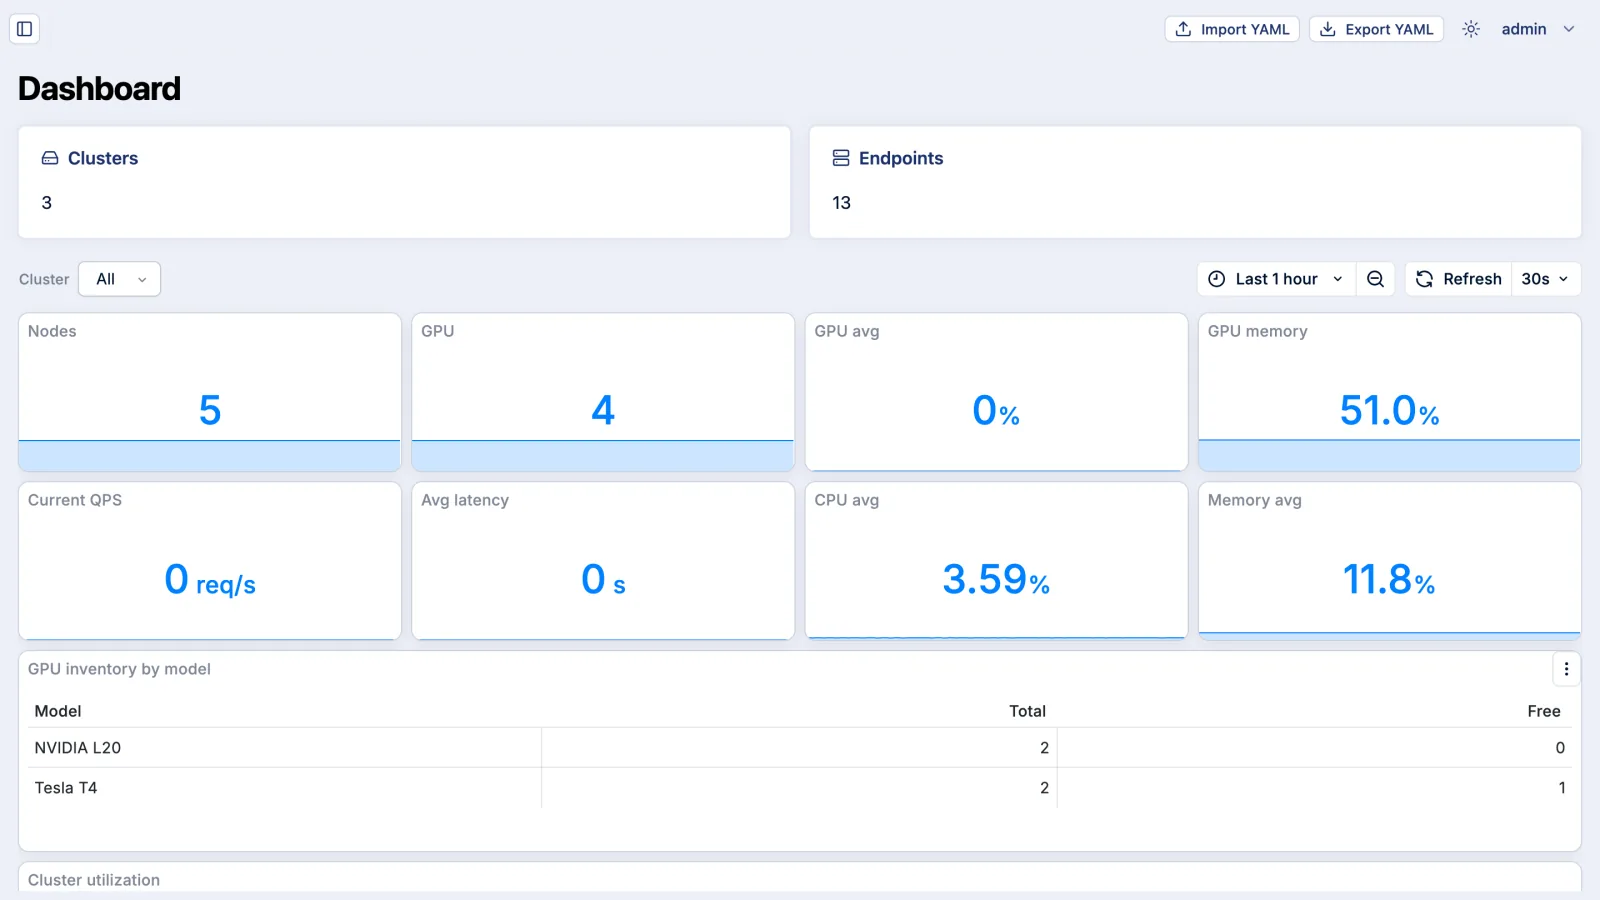
DashboardImport YAMLExport YAMLadmin
Clusters3
Endpoints11
ClusterAllLast 1 hour30s
Nodes5
GPU4
GPU avg37%
GPU memory51.0%
Current QPS128req/s
Avg latency0.42s
CPU avg3.57%
Memory avg11.8%

GPU inventory by model

ModelTotalFree
NVIDIA L2021
Tesla T421

Cluster utilization

60%45%30%15%0%
10:3010:4511:0011:1511:30
CPUMemoryGPUGPU memory
Overview
Benefits
Features
Production Foundation
Customer Stories
Resources
Overview

An Infrastructure Platform for Enterprise AI Inference and Model Services

SMTX AI Platform is an infrastructure platform for enterprise AI inference and model services. It provides unified management of heterogeneous compute resources, diverse model assets, and model access points in on-premises environments, helping enterprises build a secure, efficient, manageable, governable, and observable foundation for AI services.

With a flexible and compatible architecture, the platform supports physical servers, virtual machines, and Kubernetes, as well as AI accelerators from NVIDIA, Ascend, AMD, and Intel. Through model repositories, inference engines, model gateways, resource scheduling, access governance, and observability, SMTX AI Platform reduces the complexity of model deployment and compute management, helping AI applications move from validation to production.

SMTX AI Platform Capabilities
Compute ManagementModel ManagementModel RepositoryModel CatalogModel GatewayObservability
AI Accelerators
NVIDIAGPU
AscendNPU
AMDGPU
IntelGPU
Runtime Environments
Physical Server
Virtual Machine
Kubernetes
Benefits

Why SMTX AI Platform?

Unified Management, Day-1 Model Availability

An open architecture brings heterogeneous compute across physical, virtualized, and containerized environments under unified management, abstracting underlying differences and centrally managing all models. Deploy the platform in one day and make models available on Day 1.

Higher Resource Utilization, Lower AI Infrastructure Costs

Deploy the platform wherever you need it and support diverse workloads while making full use of existing infrastructure and reducing duplicate investment. Centrally managed models can be reused across applications. GPU virtualization and fine-grained partitioning by memory and compute capacity enable more precise and efficient resource utilization.

Stronger Model Governance, More Granular Operations

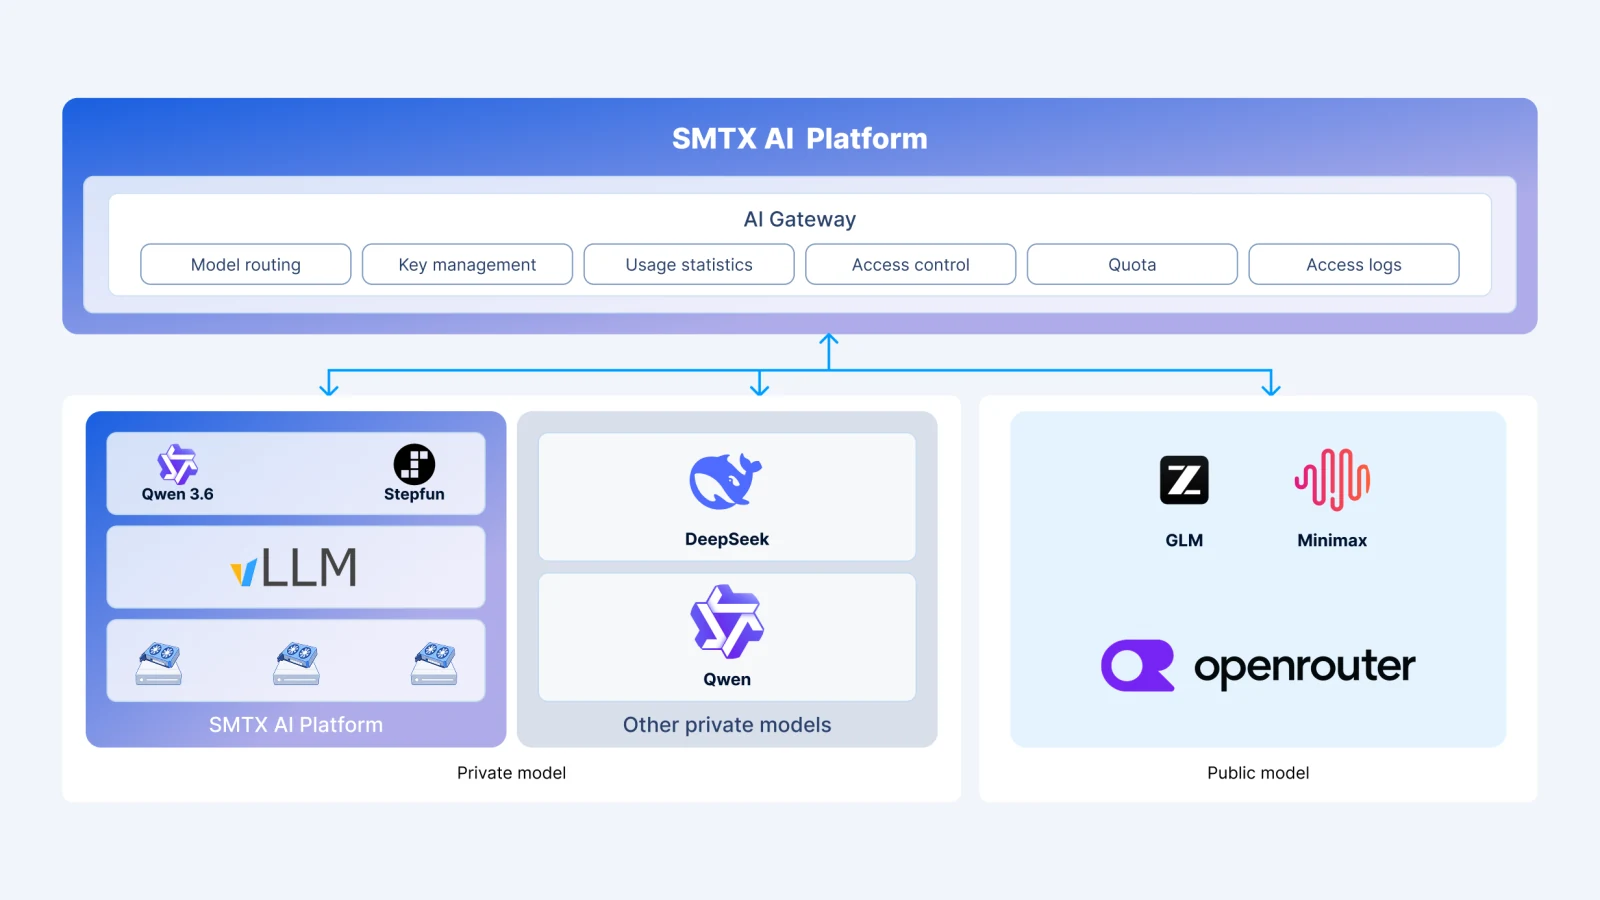
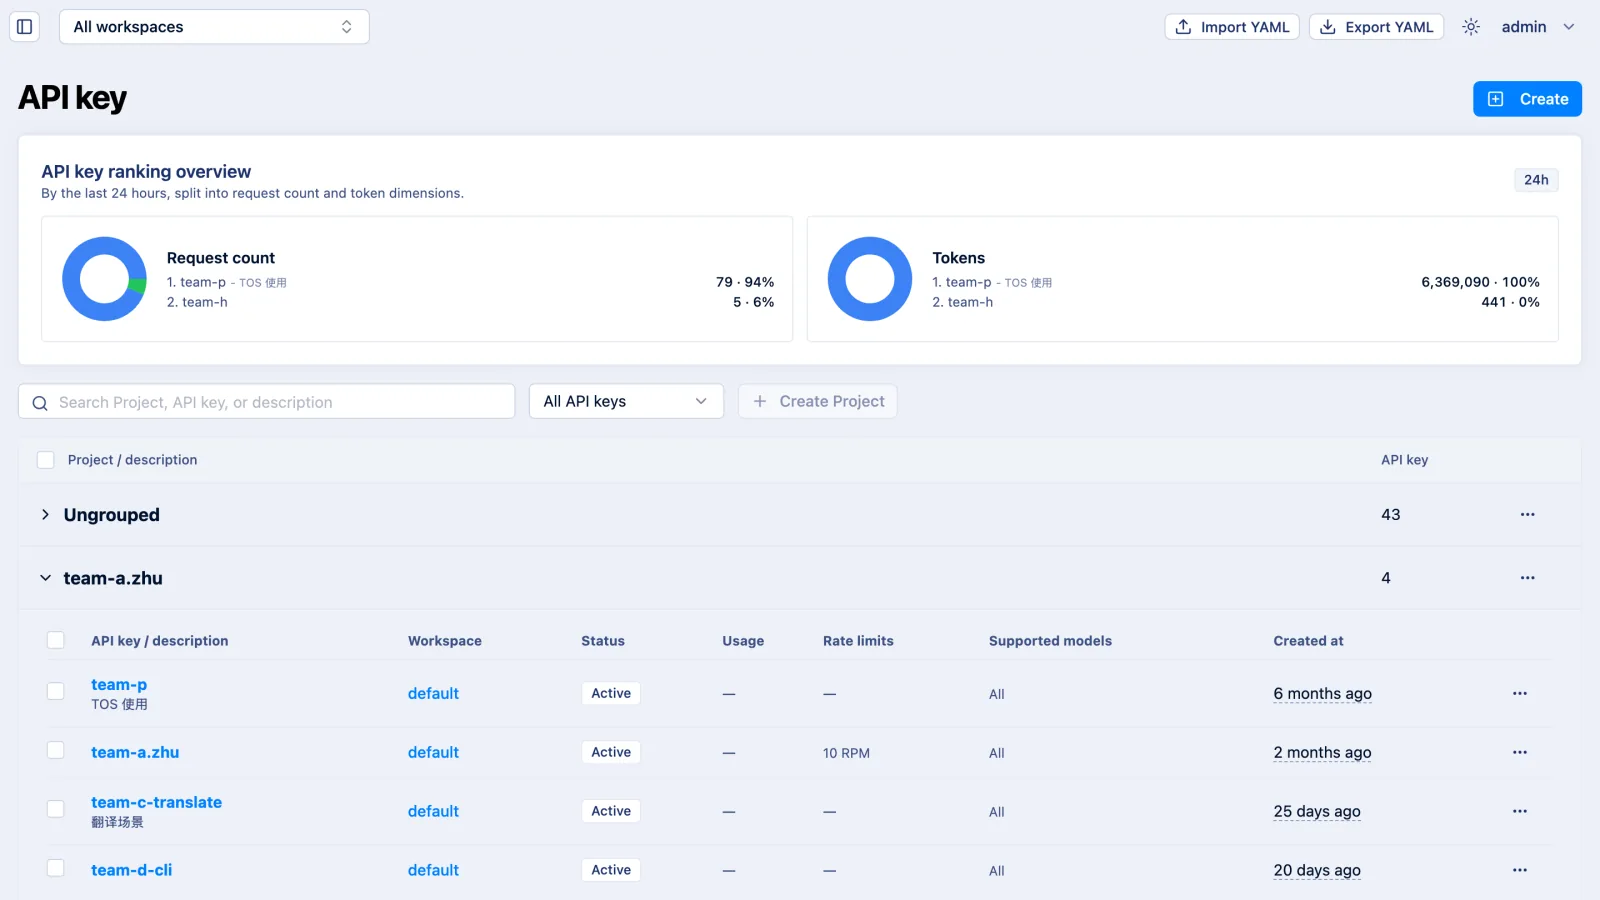
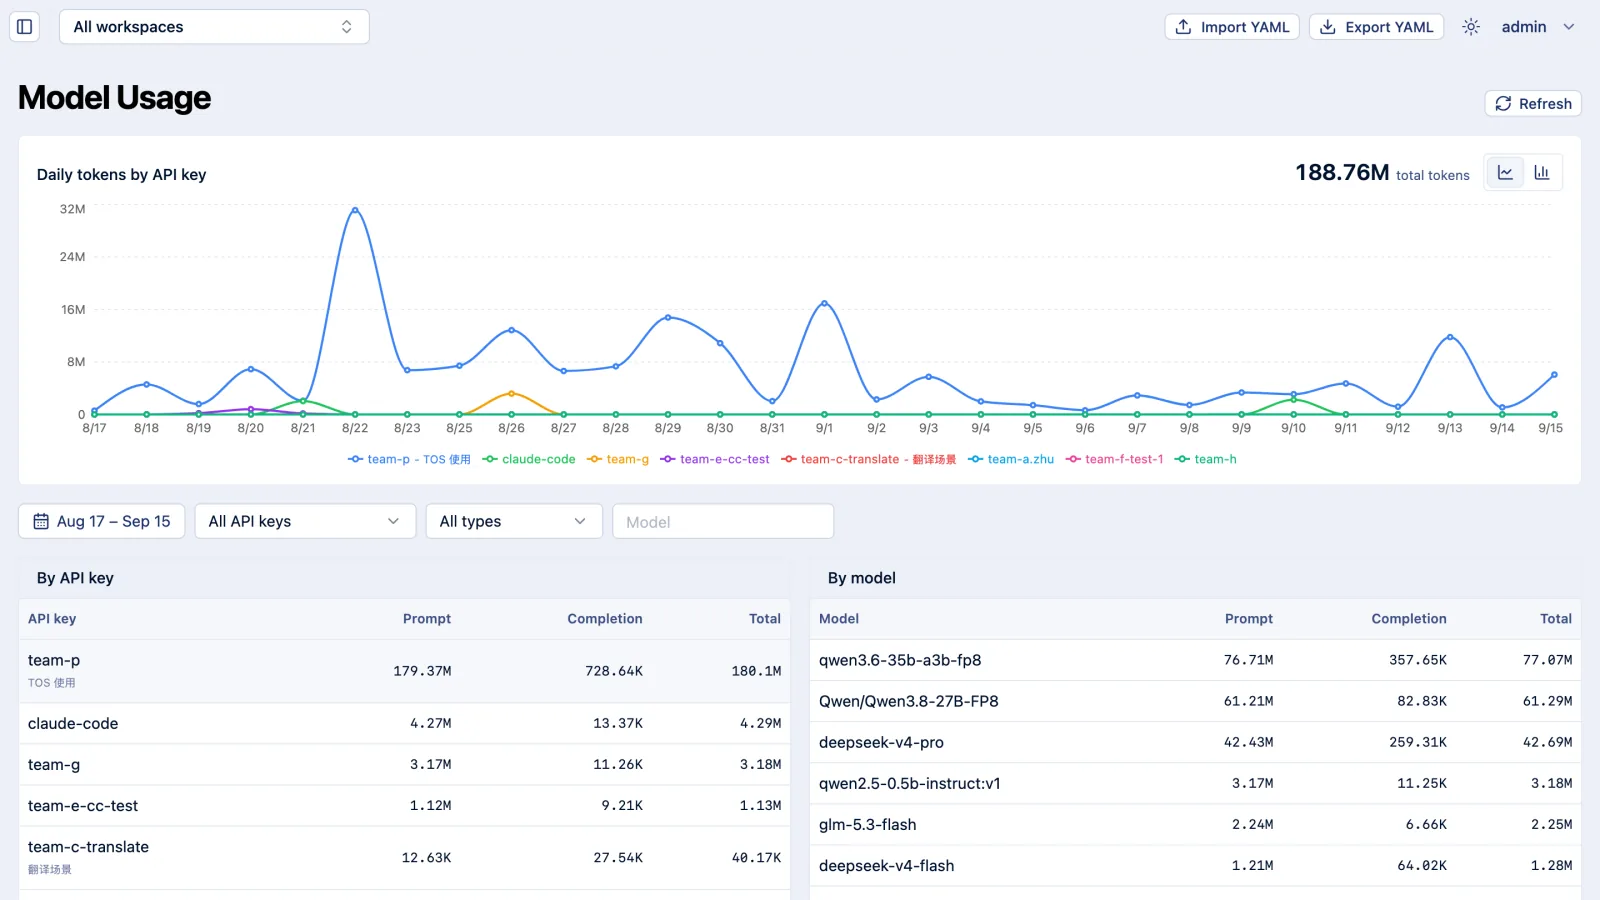
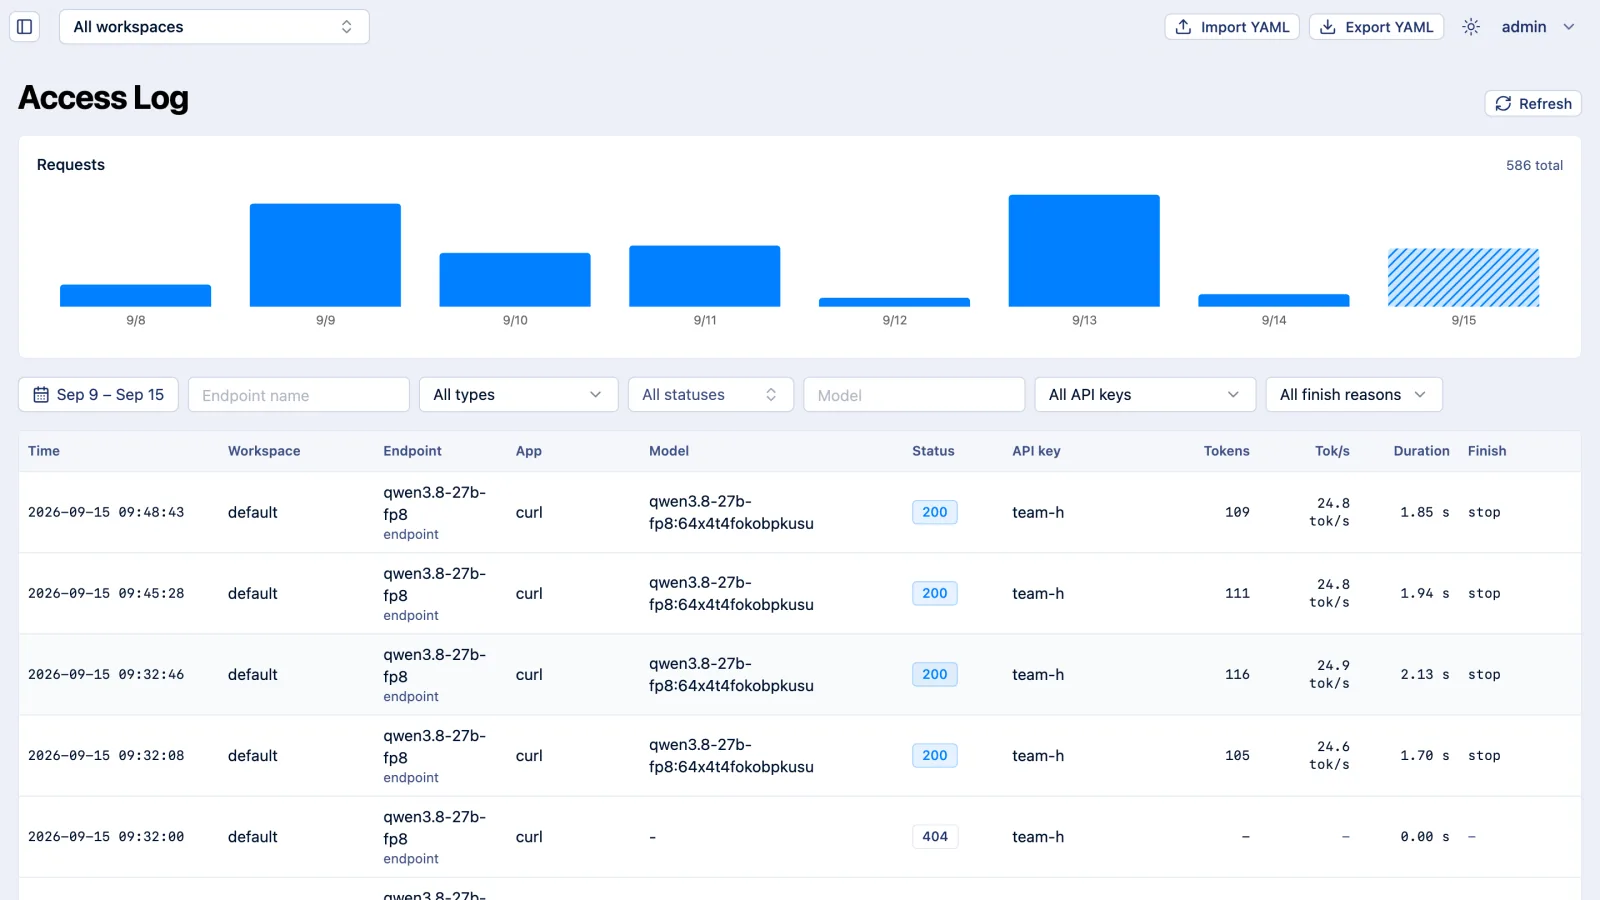
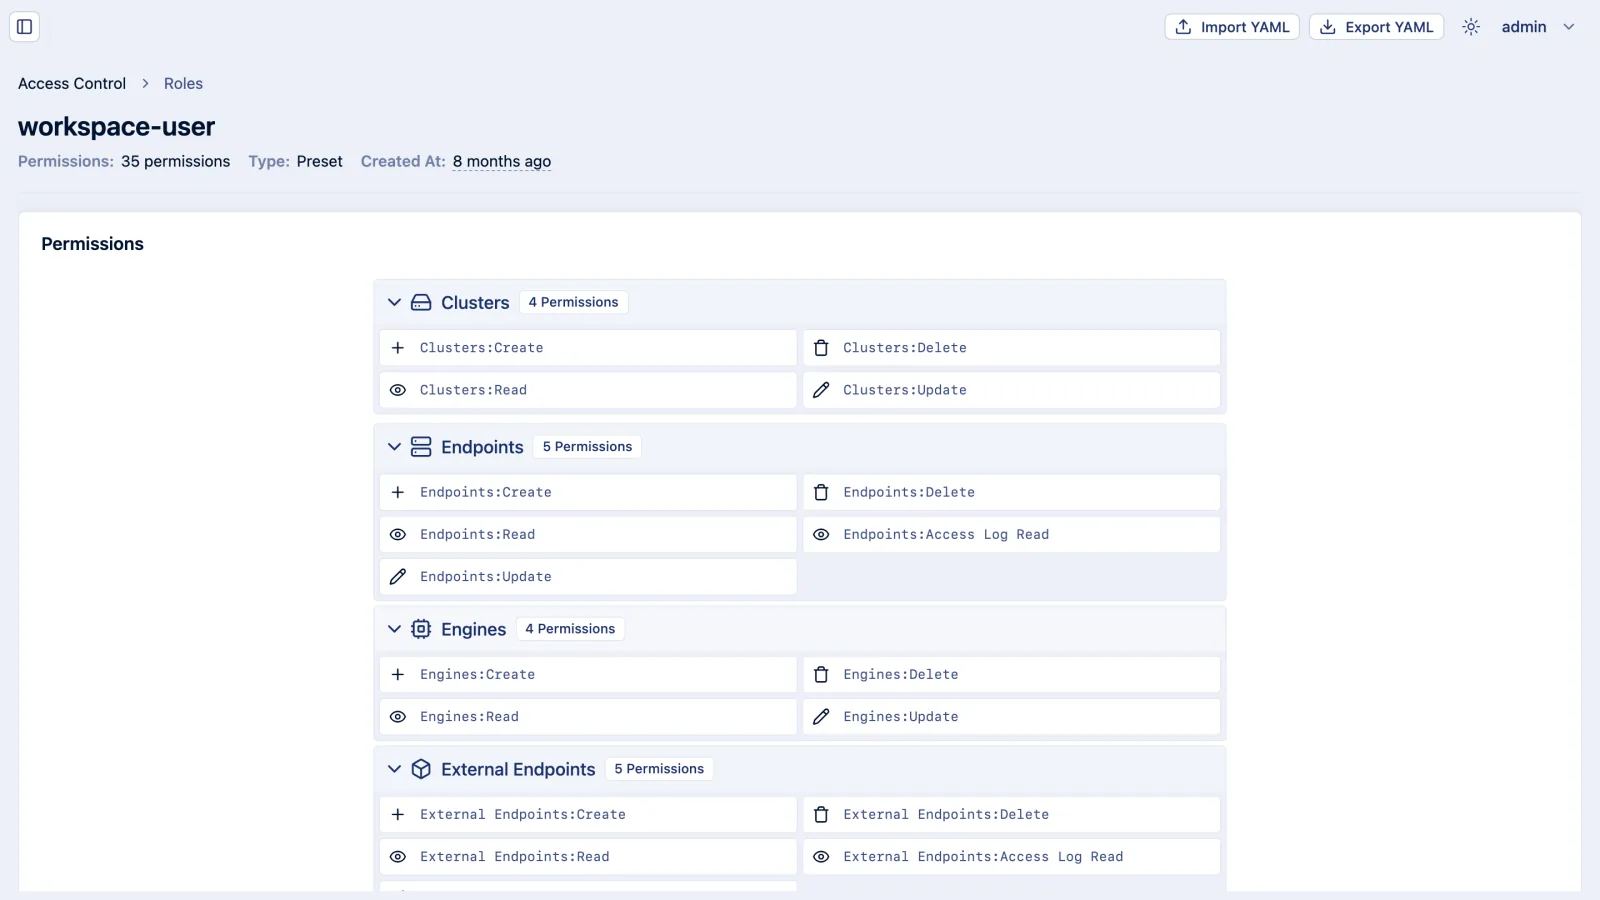
The built-in model gateway provides unified usage statistics, token quotas, access logs, and access control, making model usage visible, controllable, auditable, and measurable.

Production-Grade Foundation for Reliable Inference Services

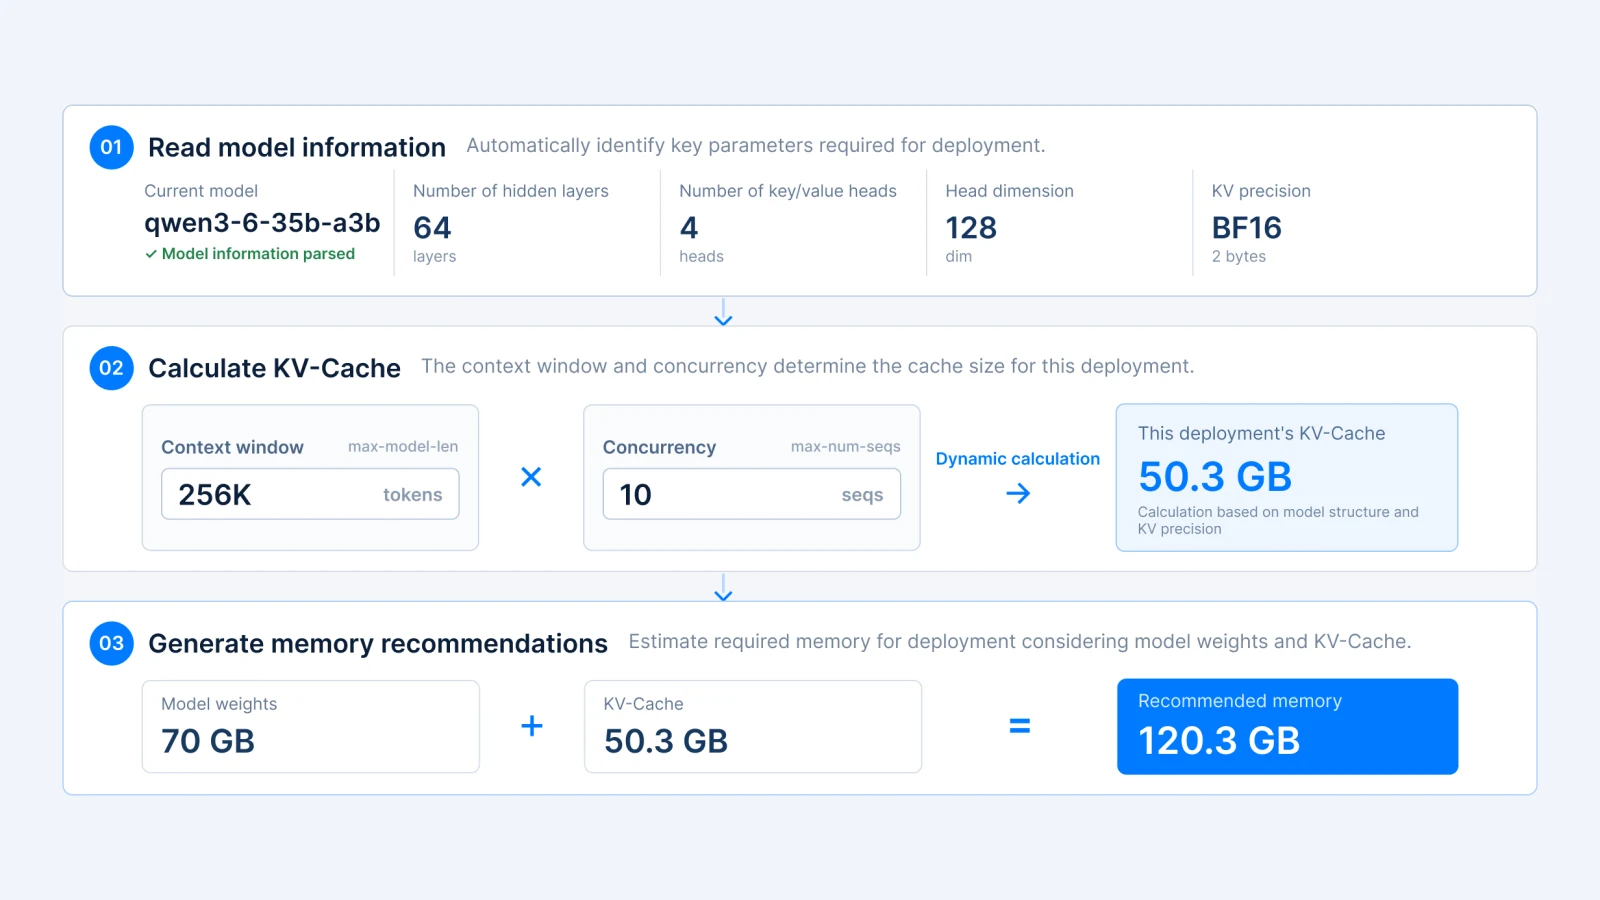
Inference services support high availability with multiple replicas, load balancing, and native KV Cache offloading. Backed by production-grade container and storage services, unified monitoring, and logging, SMTX AI Platform delivers lightweight, stable, and observable inference services for continuous business operations.

Features

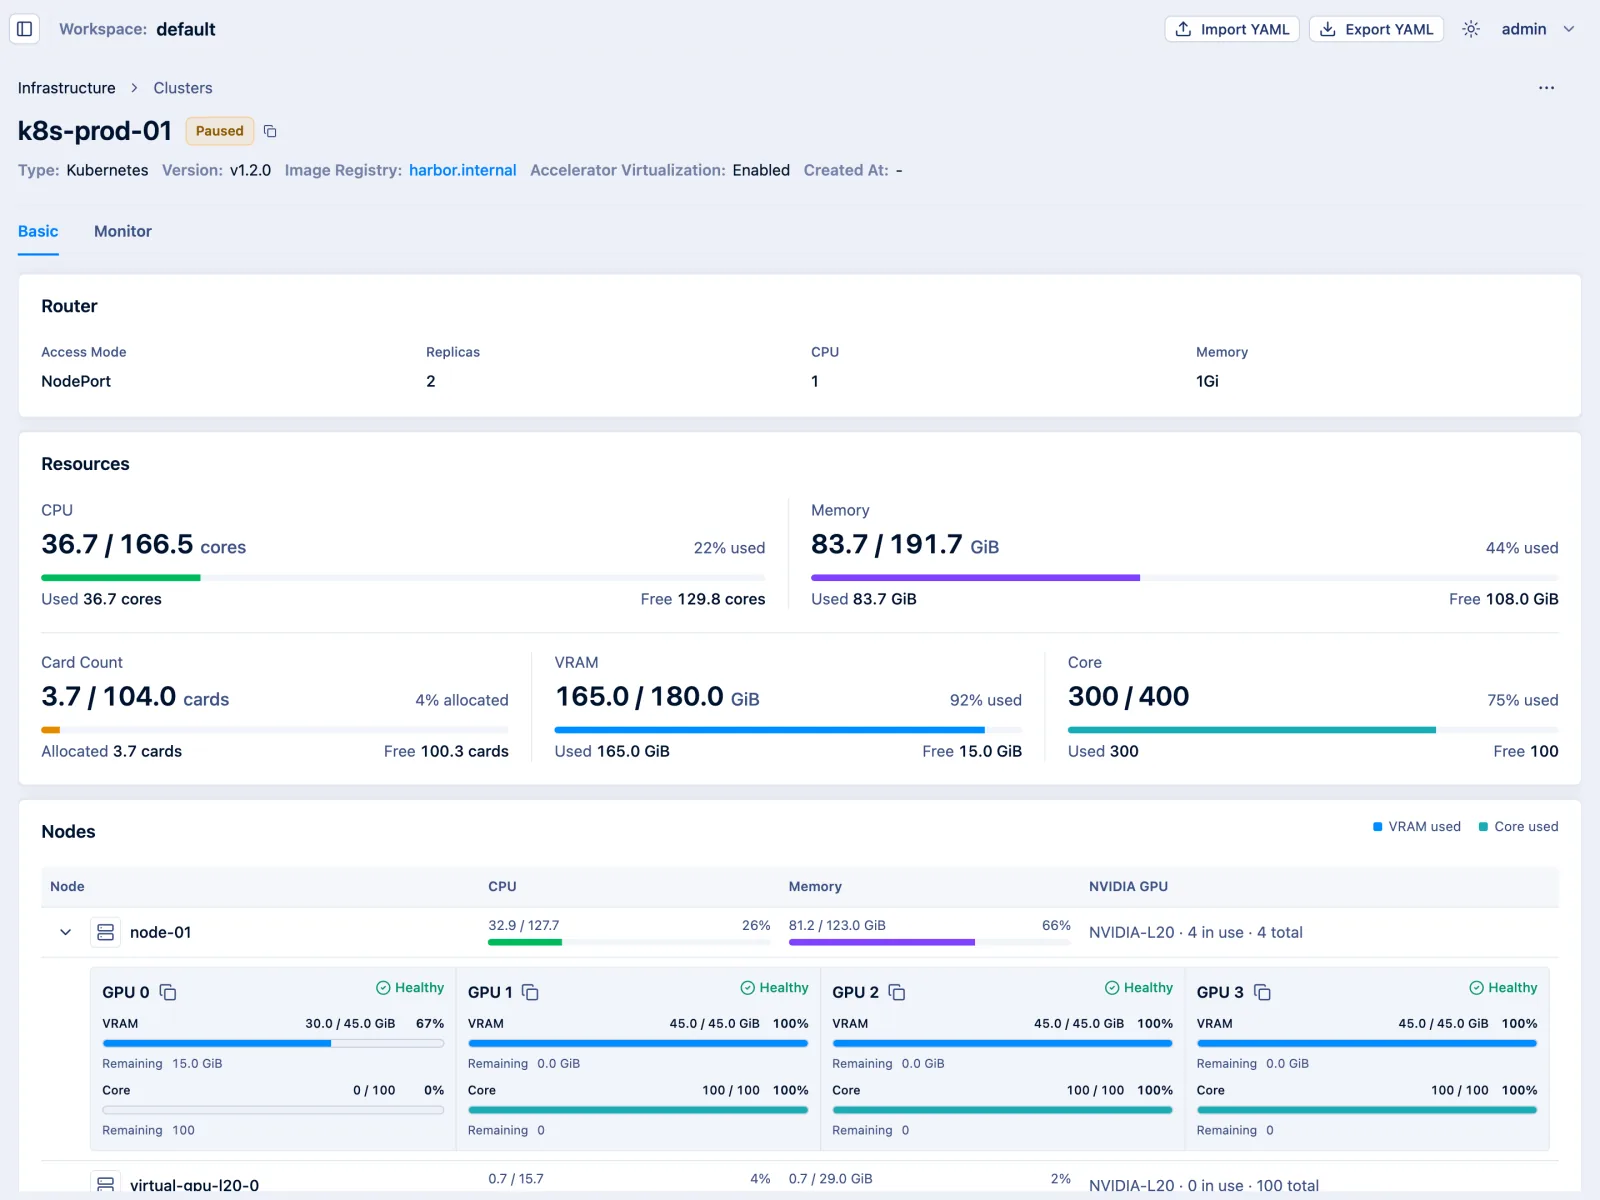
Unified Heterogeneous AI Compute Management

SMTX AI Platform cluster detail screen showing cluster CPU, memory, accelerator and VRAM usage together with per-node GPU status
Unified Heterogeneous AI Compute Management
  • Unified Compute Across Environments

    Bring AI compute from physical servers, virtual machines, and Kubernetes clusters under unified platform management. Abstract environment differences and enable consistent resource scheduling, monitoring, and allocation.

  • Unified Management of Diverse AI Accelerators

    Manage heterogeneous AI accelerators from NVIDIA, Ascend, AMD, and Intel, including GPUs and NPUs. Centrally manage existing and new compute resources, reduce duplicate infrastructure investment, improve reuse, and support domestic and heterogeneous compute requirements.

  • Elastic Compute Orchestration

    Dynamically partition NVIDIA GPUs, Ascend NPUs, and other heterogeneous resources, or pass through entire devices according to model size and performance requirements. Use full-device passthrough for large-model inference to maintain stable performance and throughput; share partitioned resources across lightweight OCR, ASR, embedding, and reranking models to balance performance, utilization, and cost.

Unified Delivery of Diverse Models

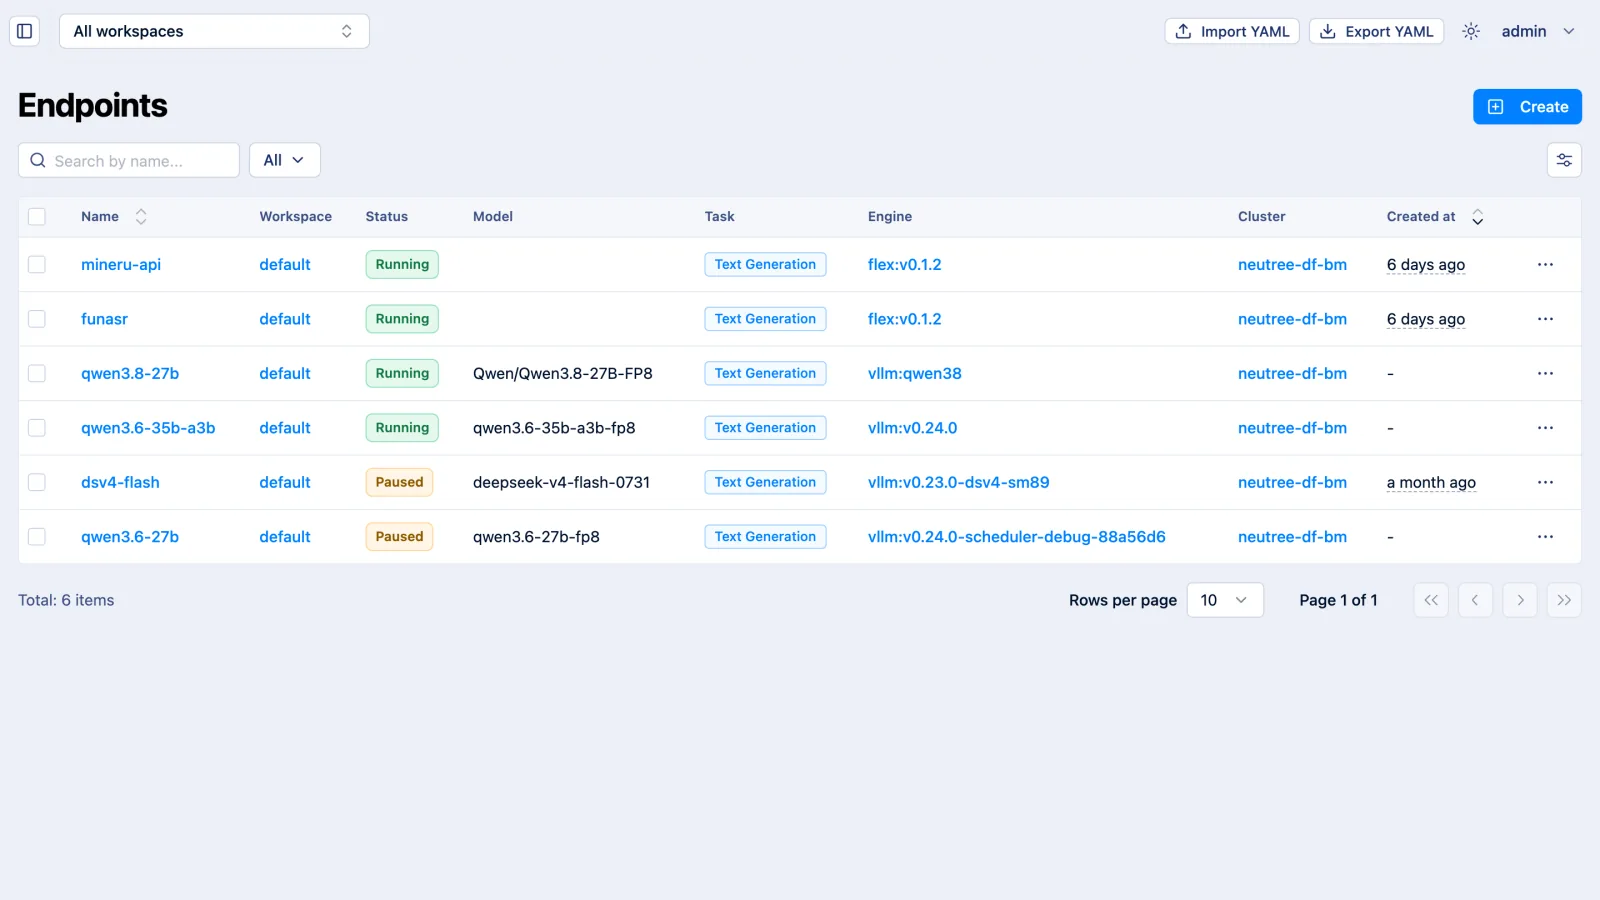
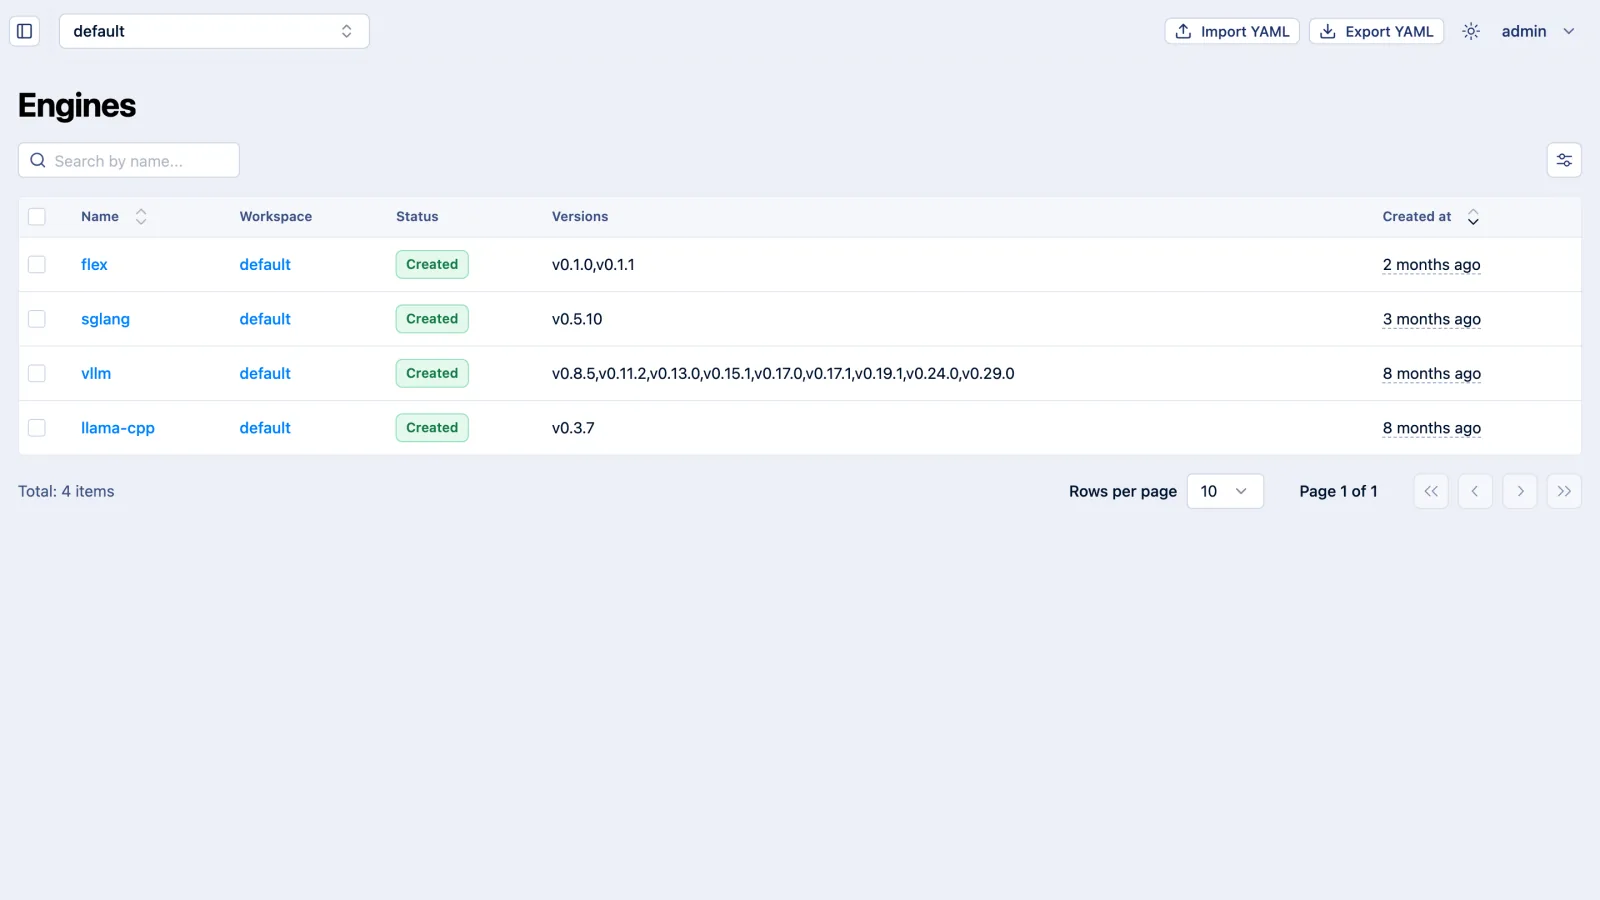
Inference instance list view
Unified Management of Multiple Model Types

Unified Management of Multiple Model Types

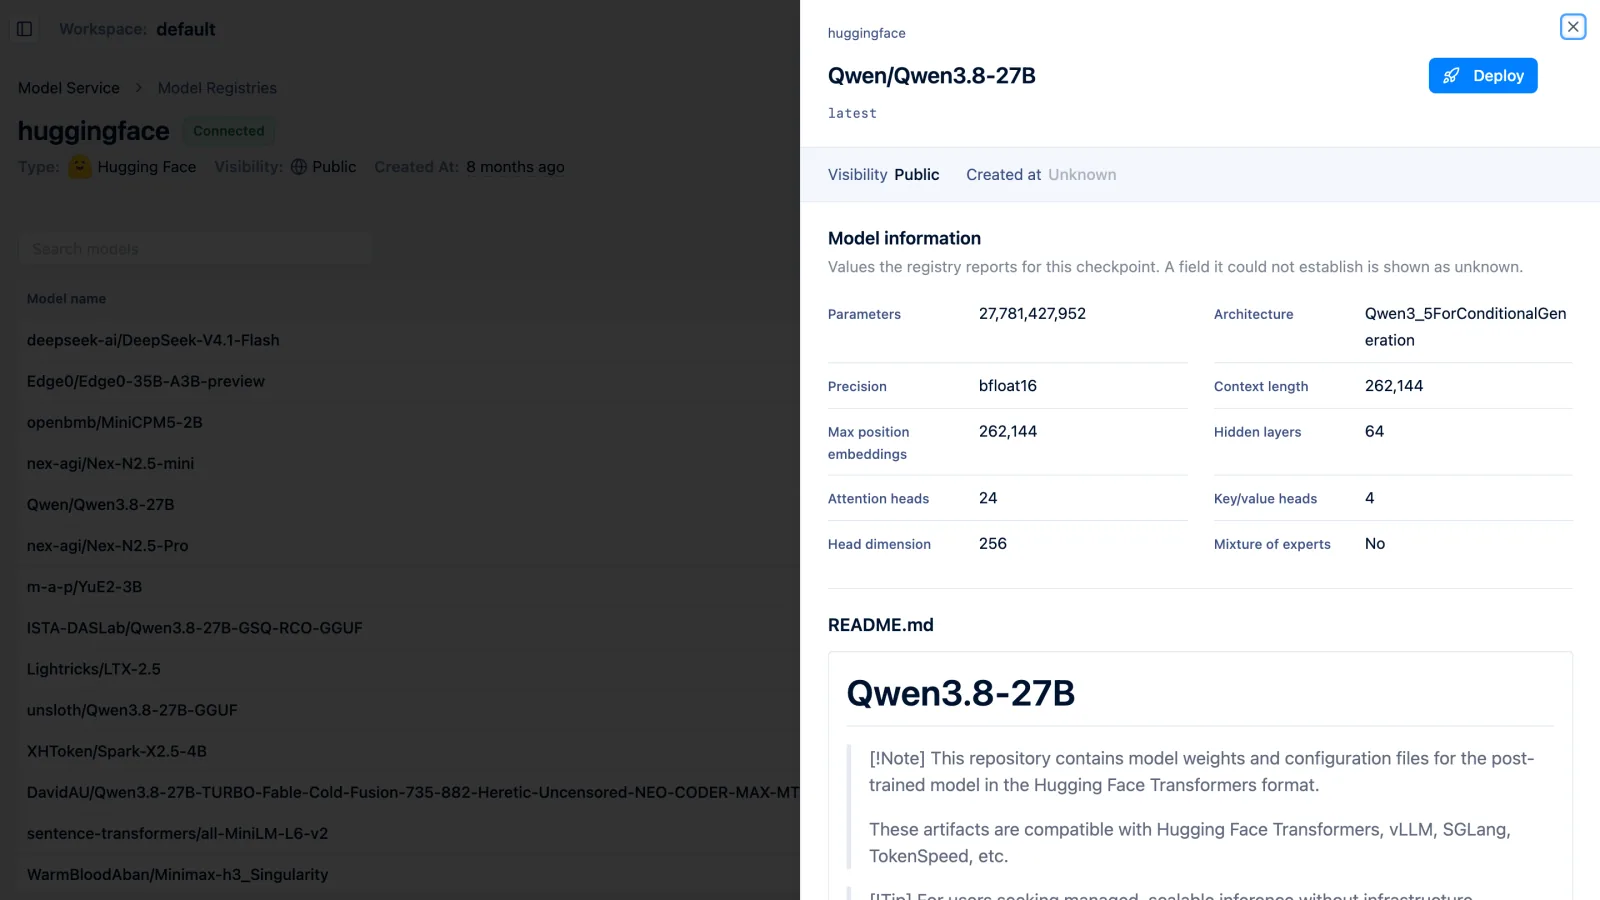
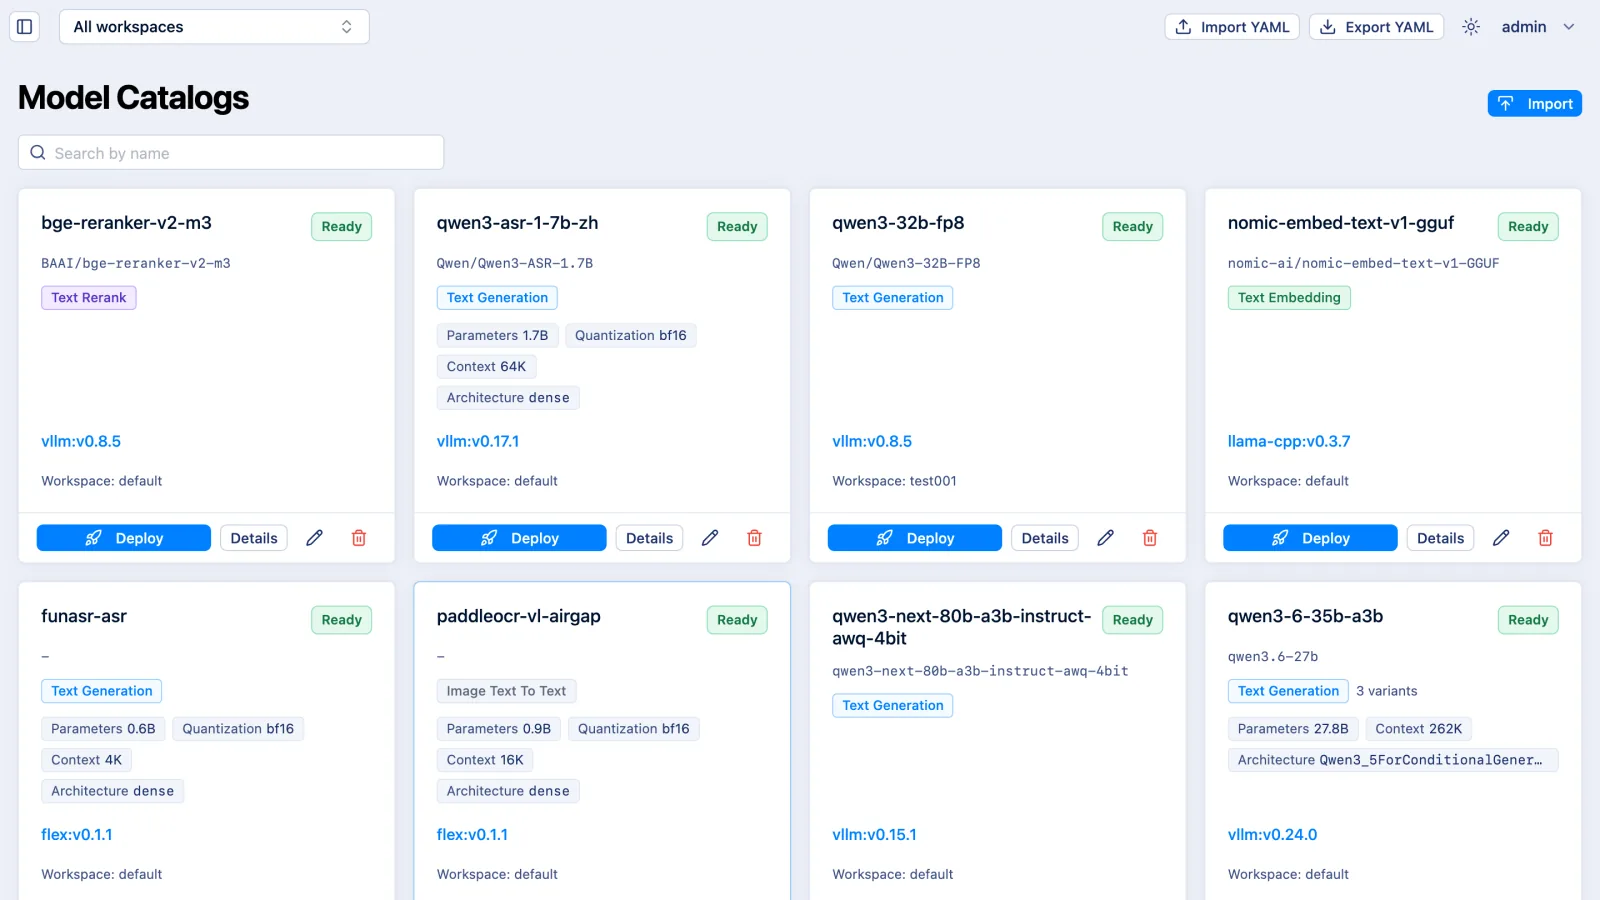
Centrally manage large language models, multimodal models, embedding and reranking models, and vision models. Flex Engine extends support to MinerU, PaddleOCR, and selected machine-learning models, enabling deployment, publishing, and access to language, vision, document-processing, OCR, and machine-learning assets on one platform.

Model Gateway and Governance

Diagram: private and public models reached through one entry point
One Access Point for Internal and External Models

One Access Point for Internal and External Models

Connect private models, public models, and external model APIs through a unified model gateway. Applications use a consistent interface across models, minimizing changes to endpoints, authentication methods, and integration settings when models change.

Unified Operations and End-to-End Observability

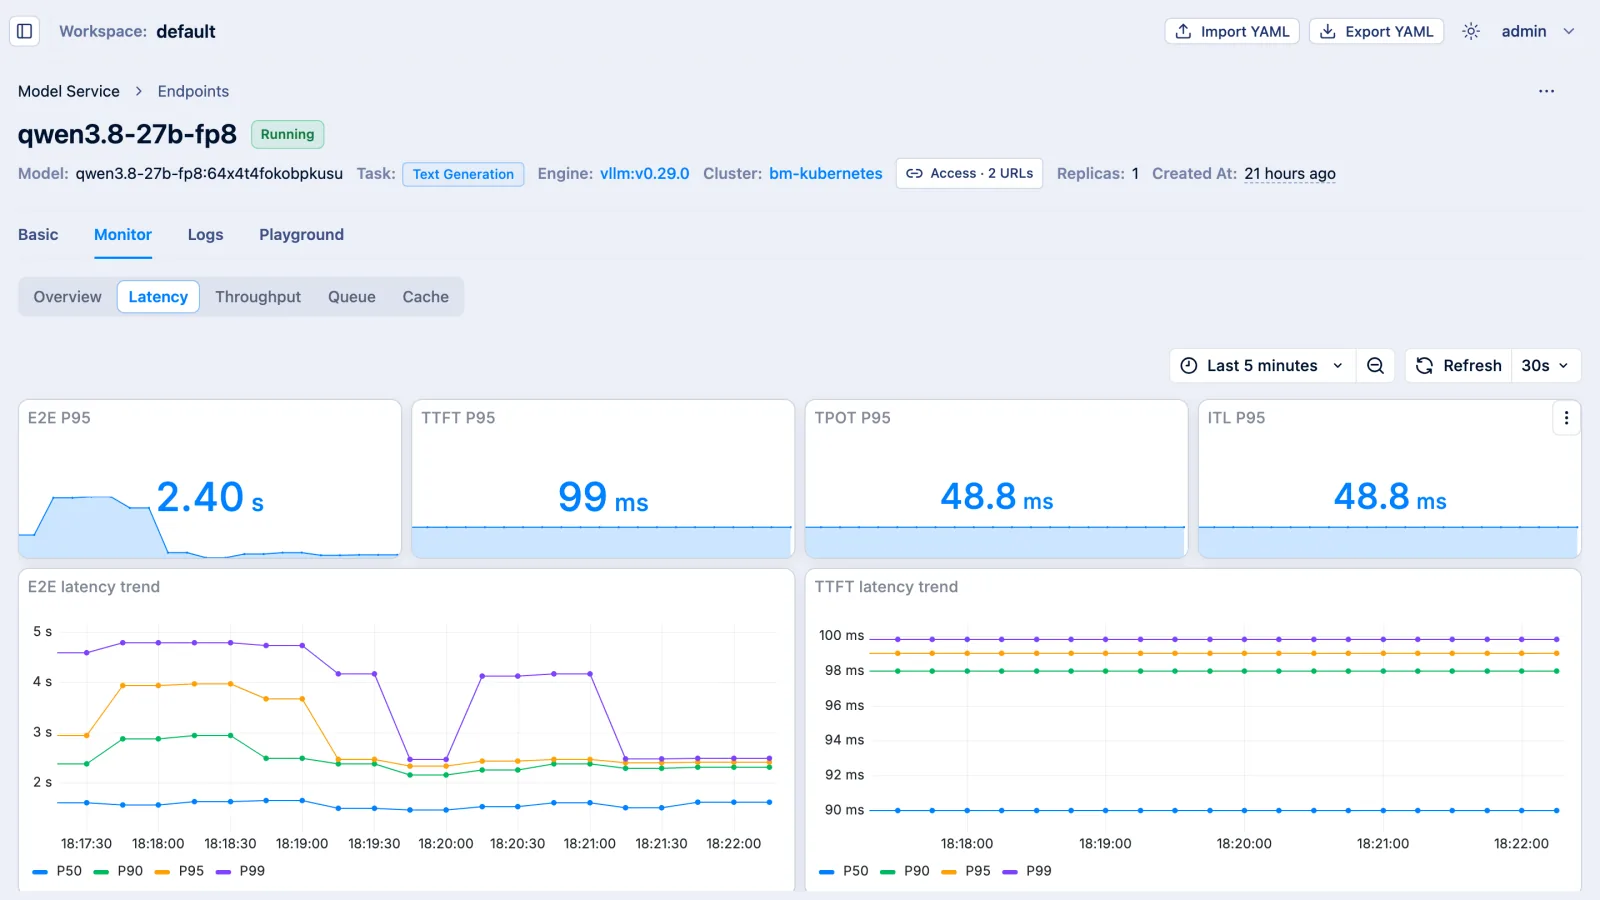
Latency panel of an inference instance: P95 cards for E2E, TTFT, TPOT and ITL, above the P50-P99 latency trend charts
Observable Model-Service Runtime

Observable Model-Service Runtime

View inference-instance health, real-time logs, TTFT, TPOT, end-to-end latency, throughput, queue depth, and KV Cache usage to quickly identify performance bottlenecks and runtime anomalies.

Production Foundation

Build Production-Grade AI Inference Infrastructure

SMTX AI Platform is an AI-inference component of the SmartX Enterprise Cloud Platform. It focuses on compute and model management, model governance, and high-performance inference. Together with the container, storage, networking, security, and observability capabilities of the SmartX Enterprise Cloud Platform, it helps enterprises build production-grade, high-performance, and governable model-inference infrastructure.

SMTX AI Platform
SmartX Enterprise Cloud Platform
Container Services

Provide a standardized runtime for model inference, GPU driver management, and high-performance networking for stable inference and efficient scheduling.

Storage Services

Provide shared, manageable storage for model files, reducing duplicate storage and distribution. High-performance, high-capacity storage also supports KV Cache caching and persistence.

Observability

Cover GPU hardware, container status, inference health, model resource consumption, access logs, token usage, and end-to-end latency to support troubleshooting, security audits, performance assessment, and continuous optimization.

Customer Stories

AI Infrastructure in Production Across Scenarios

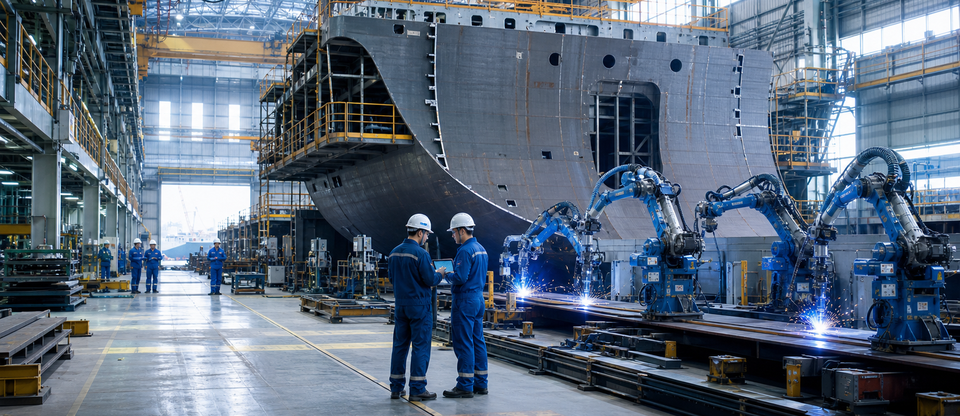
Illustration for the shipbuilding engineering company agent and model support case
Agent Operations + Model ServicesManufacturing

Large Shipbuilding Engineering CompanyBuild intelligent agents & end-to-end model support

SmartX Enterprise Cloud Platform / SMTX AI Platform

The SmartX Enterprise Cloud Platform supports internal applications such as regulatory guidance, translation, and operations. SMTX AI Platform provides unified management and governance for existing and custom-built models.

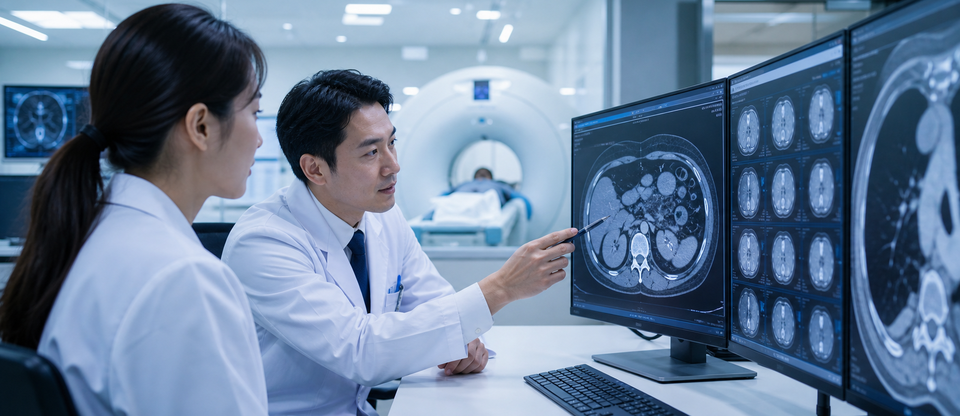
Illustration for the Grade-A tertiary general hospital model-as-a-service case
Model ServicesHealthcare

Grade-A Tertiary General HospitalBuild a unified model-as-a-service platform

SMTX AI Platform

Based on SMTX AI Platform, the hospital centrally manages compute and models to support diverse AI applications.

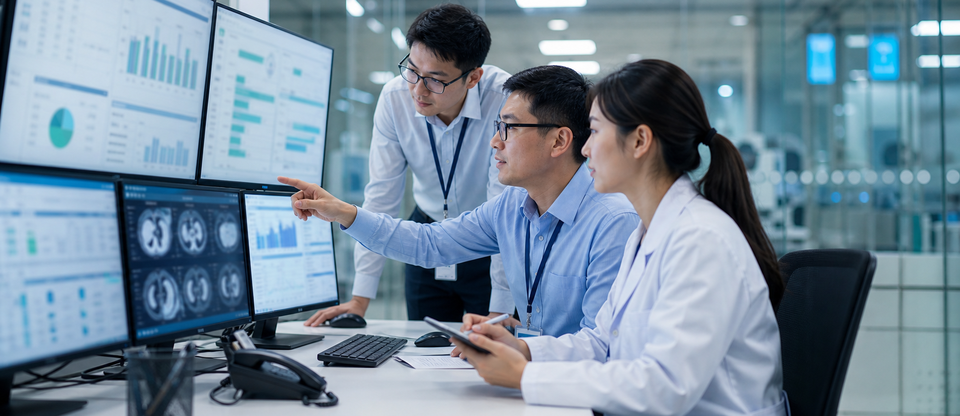
Illustration for the Grade-A tertiary general hospital unified compute and model delivery case
Unified Compute & Model DeliveryHealthcare

Grade-A Tertiary General HospitalDeliver compute and model resources through one unified platform

SmartX Enterprise Cloud Platform / SMTX AI Platform

The SmartX Enterprise Cloud Platform provides the compute resources for video analytics and other lightweight models, while SMTX AI Platform enables unified management of large language models.